
What is Decibri?
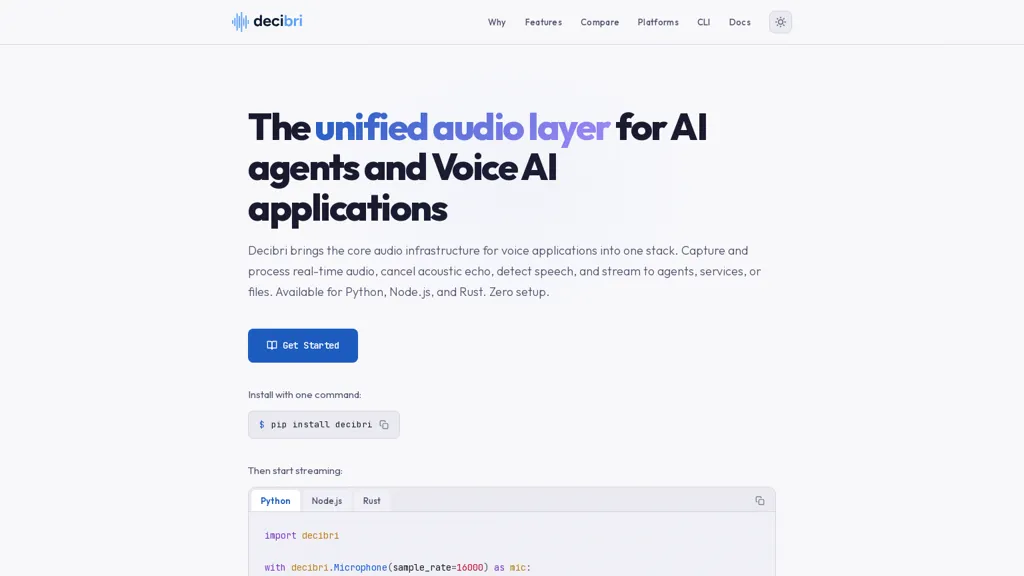
Decibri provides a unified audio layer for real-time voice applications, offering cross-platform microphone capture, speaker playback, and local voice activity detection.
Pre-built binaries for Python, Node.js, and Rust remove the need for platform-specific build tools and simplify installation.
Direct OS audio access eliminates subprocesses and intermediate encoding, enabling predictable low-latency capture and stream-native APIs (Python iterators, Node Readable streams, Rust channels).
Features include acoustic echo cancellation, configurable capture parameters, and a speaker API for full-duplex audio routing.
A bundled VAD model runs locally to emit speech/silence events without cloud calls; the package also provides a browser-compatible AudioWorklet build.
Decibri outputs raw PCM for easy integration with speech-to-text engines and streaming pipelines, and includes helpers for recording to disk and piping audio to WebSockets or services.
Type definitions and async APIs enable IDE autocomplete and non-blocking capture in async event loops.
Decibri pricing
FreemiumDecibri offers a free plan with paid upgrades available.
Verify on the official pricing page.
View plansDecibri's key features
-
Cross-platform unified audio layer for real-time apps: microphone capture and speaker playback
-
Pre-built binaries for Python, Node.js, and Rust (no platform-specific build tools)
-
Direct OS audio access enabling low-latency capture and stream-native APIs (Python iterators, Node Readable streams, Rust channels)
-
Built-in audio processing: acoustic echo cancellation, configurable capture parameters, and speaker API for full-duplex routing
-
Bundled local VAD model emitting speech/silence events and a browser-compatible AudioWorklet build
Decibri use cases
-
Build a low-latency, cross-platform multiplayer voice chat for games using Decibri's direct OS access and prebuilt Python/Node/Rust binaries to capture real-time microphone audio, route full‑duplex streams, apply local VAD and acoustic echo cancellation for clear voice, and output raw PCM for custom in-game processing or network streaming
-
Create a real-time voice assistant or transcription pipeline that captures low-latency microphone audio with local VAD and AEC, streams raw PCM via Decibri's streaming APIs to speech-to-text or LLM backends, and uses the provided recording and routing helpers to manage multi-mic setups and synchronized transcripts
-
Develop a live podcasting or remote music-collaboration app that records multi-channel audio with raw PCM output and acoustic echo cancellation, leverages Decibri's full‑duplex routing to mix local and remote participants with minimal latency, and deploys quickly across platforms using the prebuilt binaries
Decibri user reviews
Would you recommend Decibri?
Who is Decibri for?
-
Real-time voice application developers
-
Speech-to-text / asr integration engineers
-
Web developers building in-browser voice features
-
Node.js, python and rust developers needing cross-platform audio capture
-
Voip, teleconferencing and call-center app developers
-
Conversational ai and voice assistant developers
-
Game developers implementing in-game voice chat
-
Audio/ml researchers and prototypers using vad and raw pcm
-
Iot and embedded developers needing low-latency audio capture
Decibri FAQ
Is Decibri free?
Partly. Decibri has a free plan with usage limits, and paid plans unlock the full feature set.
Does Decibri have an API?
Yes. Decibri offers an API, so you can call it from your own applications instead of using the interface directly.